Skip to content

Blog

Heliosearch/Solr Off-Heap Filters

Off-Heap Native Filters is the first feature we added to Heliosearch, a new open source project designed to bring Solr performance to the next level.

JVMs have never been good at dealing with large heaps. Large heaps mean lots of garbage collection work, and often means some pretty long stop-the-world GC pauses where nothing else can proceed. This can cause query/request timeouts, or even zookeeper session timeouts in SolrCloud mode.

Heliosearch/Solr has some pretty advanced filter caching, but it can take up a significant amount of memory, depending on the application. This is exactly the type of large, longer lived objects that can benefit by being moved off the JVM heap and explicitly managed. Off-heap memory is invisible to the garbage collector.

Heliosearch filters (Solr DocSet objects) are now allocated off-heap and reference counted so they can be freed as soon as they are no longer being used. The JVM GC no longer needs to waste time copying around these blocks of memory. This helps to both eliminate the long GC pauses as well as increase request throughput.

I expected that I’d have to try a lot of different things to re-create the stop-the-word GC pauses reported by others, but they happened on my first try! They weren’t as big as others reported, but my heap size is small as those things go. Bigger heaps are correlated with bigger GC pauses.

  • Ubuntu Linux server, 8GB RAM, 4 CPU Cores, Java 1.7 64 bit
  • Client: 8 threads, each doing a query of an id with a random filter (500 different filters)
  • filterCache: size=1000, large enough to hold all filters w/o evictions
  • Index: 3.8GB, 50M docs

  Apache Solr command line:

java -jar -Xmx4G start.jar

  Heliosearch/Solr command line:

java -jar start.jar

  I had to set the heap size to 4GB when running Apache Solr to avoid OOM exceptions. Since the maximum amount of RAM on the box was 8G, I wanted to leave the remaining memory for the OS to cache the index files (else things would get really slow).

Here are the graphs of the resulting GC activity for a run of 20,000 query requests. The grey bars represent time spent in a GC. The red line is the actual size of the heap, and the blue line represents the actual amount of the heap in use.

It was even easy to externally see the stop-the-world pauses on Solr while the test was running. Logging was enabled, so every request left a log message, causing the terminal to rapidly scroll. Whenever a major GC compaction hit, the terminal abruptly stopped scrolling. solr_gc

The Heliosearch GC graph completes sooner because less time is spent doing garbage collection. Notice the almost complete absence of stop-the-world full GC pauses, and greatly reduced other GC pauses. heliosearch_gc

This chart shows percentile query latencies of the second 10,000 queries in a 20,000 query run (just to ensure hotspot and the caches were all warmed up).

query_latency

query_throughput The Query Throughput graph illustrates just how much CPU time is spent in garbage collection that can be freed up with off-heap data structures. This is an extreme result of course. The throughput increase caused by off-heaping data structures would be more moderate if one is not experiencing frequent large garbage collections.

The maximum resident memory of the process (monitored externally via top) was measured over 5 runs.

Apache Solr Heliosearch
minimum run 3.8 GB 3.6 GB
maximum run 4.3 GB 3.7 GB

Heliosearch, with it’s off-heap filters, had a more stable memory profile and used less memory on average. This left more memory free for the operating system to cache index files, which is very important for good performance.

In this simple test, off-heap filters eliminated long GC pauses, made requests more predictable by reducing large outliers, and increased overall query throughput.

Try it yourself and give us feedback in the Heliosearch Forum!
Getting Started with Solr

Getting Started with Solr: a Simple Solr Tutorial

Section titled “Getting Started with Solr: a Simple Solr Tutorial”

Note: this tutorial is for Solr 4

Download Apache Solr 4.

You only need to download the single .ZIP or .TGZ file and extract it anywhere you like - no installation is required!!

$ cd example
$ java -jar start.jar

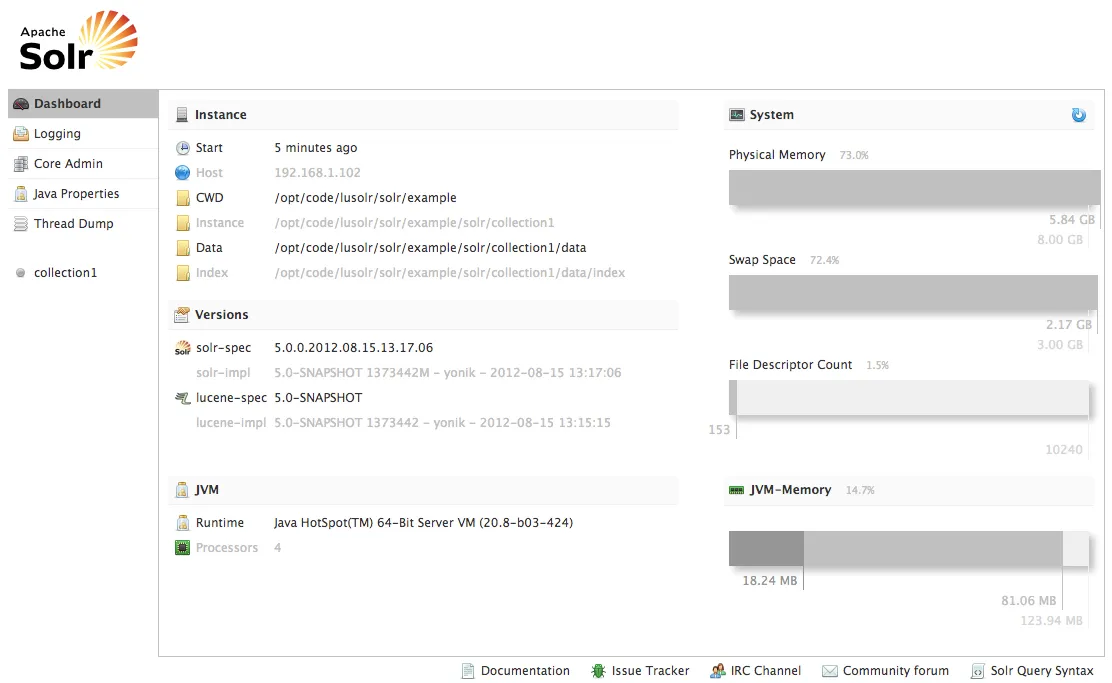
You’re now ready to start using Solr! To verify it’s up and running, you can point your browser at the admin page:

http://localhost:8983/solr/

Solr Admin

If something didn’t work, check if you have the proper prerequisites.

Now that Solr is running, we can add a document (also known as “indexing” a document):

$ curl http://localhost:8983/solr/update -H 'Content-type:application/json' -d '
[
{"id" : "book1",
"title" : "American Gods",
"author" : "Neil Gaiman"
}
]'

And then we can ask for it back:

$ curl http://localhost:8983/solr/get?id=book1
{
"doc": {
"id" : "book1",
"author": "Neil Gaiman",
"title" : "American Gods",
"_version_": 1410390803582287872
}
}

Of course for queries, you can always just use your browser and click on the link http://localhost:8983/solr/get?id=book1 or cut’n’paste the URL into your browser and modify the query directly in the address bar to try out different requests.

The author and title fields are pre-defined in the schema, but Solr can use convention over configuration for new fields if one does not wish to edit the schema. In this manner, Solr includes the essential benefits of schemaless - namely the ability to add new fields on the fly without having to pre-define them.

Let’s update book1 with cat, a category field, and two new fields that haven’t been defined in the schema, a publication year, and an ISBN. Via dynamic fields, a field name ending with _i tells Solr to treat the value as an integer, while a field name ending with _s is treated as a string.

$ curl http://localhost:8983/solr/update -H 'Content-type:application/json' -d '
[
{"id" : "book1",
"cat" : { "add" : "fantasy" },
"pubyear_i" : { "add" : 2001 },
"ISBN_s" : { "add" : "0-380-97365-0"}
}
]'

By using convention via dynamicFields, Solr avoids the pitfalls of trying to guess at the types of new fields while retaining the benefits of dynamically adding new fields as needed.

  Now let’s add a few more documents, this time in CSV (comma separated values) format:

$ curl http://localhost:8983/solr/update?commitWithin=5000 -H 'Content-type:text/csv' -d '
id,cat,pubyear_i,title,author,series_s,sequence_i
book2,fantasy,1996,A Game of Thrones,George R.R. Martin,A Song of Ice and Fire,1
book3,fantasy,1999,A Clash of Kings,George R.R. Martin,A Song of Ice and Fire,2
book4,sci-fi,1951,Foundation,Isaac Asimov,Foundation Series,1
book5,sci-fi,1952,Foundation and Empire,Isaac Asimov,Foundation Series,2
book6,sci-fi,1992,Snow Crash,Neal Stephenson,Snow Crash,
book7,sci-fi,1984,Neuromancer,William Gibson,Sprawl trilogy,1
book8,fantasy,1985,The Black Company,Glen Cook,The Black Company,1
book9,fantasy,1965,The Black Cauldron,Lloyd Alexander,The Chronicles of Prydain,2
'

We added the commitWithin=5000 parameter to indicate that we would like our updates to be visible within 5000 milliseconds (5 seconds). The Lucene library that Solr uses for full-text search works off of point-in-time snapshots that must be periodically updated in order for queries to see new changes.

Note that although we often use JSON in our examples, Solr is actually data format agnostic - you’re not artificially tied to any particular transfer-syntax or serialization format such as JSON or XML.

  Now let’s query our book collection! For example, we can find all books with “black” in the title field:

http://localhost:8983/solr/query?
q=title:black
fl=author,title

The fl parameter stands for “field list” and specifies what stored fields should be returned from documents matching the query. We should see a result like the following:

{"response":{"numFound":2,"start":0,"docs":[
{
"title":["The Black Company"],
"author":"Glen Cook"},
{
"title":["The Black Cauldron"],
"author":"Lloyd Alexander"}]
}}


Let’s try a more advanced query that combines many elements - limiting the number of books shown for any given series to 1 by grouping documents by series_s, sorting by publication year descending, and requesting facet counts for the book category:

http://localhost:8983/solr/query?
q=*:*
&fl=id,title,series_s,pubyear_i
&sort=pubyear_i desc
&group=true
&group.main=true
&group.field=series_s
&facet=true
&facet.field=cat

We can see how easy it is to construct and understand even a complex request by stepping through the parameters:

  • q=*:* the main query, *:* matches all documents
  • fl=id,title,series_s,pubyear_i field list - the list of fields we want to return for matching documents
  • sort=pubyear_i desc sorts the list of matching documents by pubyear_i in descending order
  • group=true turns on the grouping / field-collapsing feature
  • group.main=true put the grouped documents where the main query results normally appear instead of in the grouped section of the response.
  • group.field=series_s group together matching documents by the series_s field
  • facet=true turns on the faceting feature
  • facet.field=cat get facet counts for each value of the cat field. In this example, we have 5 “fantasy” books and 4 “sci-fi” books that match the query

Notice that by using simple parameters, as opposed to a compilcated hierarchial DSL, it’s very easy to add additional request parameters without worrying about matching up braces or how they nest within a request. For example, if you wanted to get facet counts by publication year, you could simply add facet.field=pubyear_i anywhere in the list of request parameters. Simple parameter-based requests are especially valuable during ad-hoc testing where it’s easy to add, remove, and edit request parameters right in the address bar of your browser! They also play nicer with HTML forms which can directly create Solr requests from the request parameters.

Welcome to the community! Now that you’ve discovered just how easy it is to get up and running, you should check out all of the other powerful features that Solr has to offer.

Remember to subscribe to the solr-user mailing list where you’ll meet a ton of helpful users and developers!

Subscribe: solr-user-subscribe

Advanced Filter Caching in Solr

The filter caching features in Solr allow for precise control over how filter queries are handled in order to maximize performance. Solr has the ability to specify if a filter is cached, specify the order filters are evaluated, and specify post filtering.

Adding a filter expressed as a query to a Solr request is a easy… simply add an additional fq parameter for each filter query.

http://localhost:8983/solr/demo/select?
q=cars
&fq=color:black
&fq=model:Lamborghini
&fq=year:[2014 TO *]

By default, Solr resolves all of the filters before the main query. Each filter query is looked up individually in Solr’s filterCache (which is pretty advanced itself, supporting concurrent lookups, different eviction policies such as LRU or LFU, and auto-warming). Caching each filter query separately accelerates Solr’s query throughput by greatly improving cache hit rates since many types of filters tend to be reused across different requests.

Update: starting with Solr 5.2, there is support built directly into the standard query parser for creating a filter query that uses the filter cache.

The advanced filter control API adds the ability to *not* cache a filter. Some filters may see almost no reuse across different requests, and not caching them can lead to a smaller, more effective filterCache with a higher hit rate.

To tell Solr not to cache a filter, we use the same powerful local params DSL that adds metadata to query parameters and is used to specify different types of query syntaxes and query parsers. For a normal query that does not have any localParam metadata, simply prepend a local param of cache=false. For example:

&fq={!cache=false}year:[2014 TO *]

To add cache=false to a filter query that already had localParams, simply add it right in with the rest of the params. For example, if we want to use Solr’s native spatial abilities to restrict our matches to locations within 50 km of Stanford, our filter query would look like:

&fq={!geofilt sfield=location pt=37.42,-122.17 d=50}

It’s easy to modify this filter to tell Solr not to cache it by adding cache=false in with the rest of the local parameters:

&fq={!geofilt sfield=location pt=37.42,-122.17 d=50 cache=false}

When a filter isn’t generated up front and cached, it’s executed in parallel with the main query. First, the filter is asked about the first document id that it matches. The query is then asked about the first document that is equal to or greater than that document. The filter is then asked about the first document that is equal to or greater than that. The filter and the query play this game of leapfrog until they land on the same document and it’s declared a match, after which the document is collected and scored.

Advanced filtering adds even more fine grained control by introducing the notion of cost. If there are multiple non-cached filters in a response, filters with a lower cost will be checked before those with a higher cost.

&fq={!cache=false cost=10}year:[2014 TO *]
&fq={!geofilt cache=false cost=20}
&pt=48.53,-131.26
&sfield=dealer_location
&d=50

In the example above, the filter based on year has a lower cost and will thus always be checked before the spatial filter.

As an aside, notice how spatial queries will use global spatial request parameters if they are not specified locally. This can make it even easier to construct requests containing spatial functions.

Some filters are slow enough that you don’t even want to run them in parallel with the query and other filters, even if they are consulted last, since asking them “what is the next doc you match on or after this given doc” is so expensive. For these types of filters, you really want to only ask them “do you match this doc” only after the query and all other filters have been consulted. Solr has special support for this called “post filtering”.

Post filtering is triggered by filters that have a cost>=100 and have explicit support for it. If there are multiple post filters in a single request, they will be ordered by cost.

The frange qparser has post filter support and allows powerful queries specifying ranges over arbitrarily complex function queries.

For example, if we wanted to take the log of popularity, divide it by the square root of the distance, and filter out documents with a result less than 5, we could run this as a post filter using frange:

&fq={!frange l=5 cache=false cost=200}div(log(popularity),sqrt(geodist()))

Post filtering support for the spatial filter queries bbox and geofilt has been available since Solr 4.0 too. To execute our previous un-cached spatial filter as a post filter, simply modify its cost to be greater than 100:

&fq={!geofilt cache=false cost=150}
&pt=37.42,-122.17
&sfield=location
&d=50

If you have expensive custom logic you’d like to add as a post filter (say per-document custom security ACLs), you can implement your own QParserPlugin that returns Query objects that implement Solr’s PostFilter interface. You can set the default cost or hardcode a cost higher than 100 if you want to only support post filtering. Then, you can use your custom parser as you would any other builtin query type via fq={!myqueryparser arg1=x arg2=y} and Solr will handle the rest!

In conclusion, hopefully this gives more insight into just one of many factors working under the hood to make Solr so fast. To try out the absolute latest functionality, you can always get a nightly build of trunk. Feedback is always appreciated!

MurmurHash3 for Java

I needed a really good hash function for the distributed indexing in SolrCloud. Since it is be used for partitioning documents, it needed to be really high quality (well distributed) since we don’t want uneven shards. It also needed to be cross-platform, so a client could calculate this hash value themselves if desired, to calculate which partition a given document belongs on.

MurmurHash3 is one of the top favorite new hash function these days, being both really fast and of high quality. Unfortunately it’s written in C++, and a quick google did not yield any suitable high quality port (this was back in 2011). So I took 15 minutes (it’s small!) to port the 32 bit version, since it should be faster than the other versions for small keys like document ids. It works in 32 bit chunks and produces a 32 bit hash - more than enough for partitioning documents by hash code.

It would be nice to prevent others from having to do the same thing. Since stuff like this is small enough, I simply put it under the public domain and uploaded to github. This way anyone can just copy the file or the function into their project and avoid extra dependencies and license hassles.

Here’s the code, copy away!

Fast forward to 2015, and we’re implementing hyperloglog based distributed cardinality count for the new Facet Analytics Module. That algorithm requires excellent 64 bit hashes.

The first step was to evaluate the Google Guava implementation of the 128 bit MurmurHash3 algorithm since Solr already uses the guava library. After a quick inspection, of the source code, I was disappointed. Their implementation is part of a larger hashing framework that introduces all sorts of inefficiencies.

  • The guava implementation does not match the reference C++ implementation for all seeds!
  • The implementation allocates *multiple* new objects for every hash
  • Even for hashing primitives (like int and long), the implementation creates a new byte buffer and copies in the value, then calls hash

It looks as if the Google implementation focused on hashing streams and large amounts of data and is completely inappropriate for hashing large numbers of small values.

New MurmurHash 128 bit Java implementation

Section titled “New MurmurHash 128 bit Java implementation”

I searched for another suitable implementation, but did not see one that had an appropriate license and did not do any object allocation. So I reinvented the wheel again and implemented a port myself, starting from the reference implementation.

  • Matches the reference MurmurHash3 implementation, for all seeds, so it can safely be used in multi-language scenarios where hashes must match.
  • Does not allocate any objects.
  • Public domain, so you can just copy the file into your project and not have to worry about extra licenses or extra JAR dependencies.

I also added in fmix32 and fmix64 from MurmurHash3 for quickly hashing integers and longs respectively.

If you need 32 bit hashes:

  • int - use MurmurHash3.fmix32(val)
  • long - use (int)MurmurHash3.fmix64(val)
  • float - use MurmurHash3.fmix32(Float.floatToRawIntBits(value))
  • double - use (int)MurmurHash3.fmix64(Double.doubleToRawLongBits(value))
  • bytes - use MurmurHash3.murmurhash3_x86_32

If you need 64 bit hashes:

  • int - use MurmurHash3.fmix64((long)val)
  • long - use MurmurHash3.fmix64(val)
  • float - use MurmurHash3.fmix64((long)Float.floatToRawIntBits(value))
  • double - use MurmurHash3.fmix64(Double.doubleToRawLongBits(value))
  • bytes - use MurmurHash3.murmurhash3_x64_128(value) and then just use one half (one long) of the 128bit result

This implementation is public domain, so just copy the code into your project!

Solr's Realtime Get

Solr took another step toward increasing it’s NoSQL datastore capabilities, with the addition of realtime get.

As readers probably know, Lucene/Solr search works off of point-in-time snapshots of the index. After changes have been made to the index, a commit (or a new Near Real Time softCommit) needs to be done before those changes are visible. Even with Solr’s new NRT (Near Real Time) capabilities, it’s probably not advisable to reopen the searcher more than once a second. However there are some use cases that require the absolute latest version of a document, as opposed to just a very recent version. This is where Solr’s new realtime get comes to the rescue, where the latest version of a document can be retrieved without reopening the searcher and risk disrupting other normal search traffic.

The realtime get handler is registered at the /get URL. As an example, a request like

http://localhost:8983/solr/get?id=SOLR1000&fl=id,name

returns a response like

{"doc":{"id":"SOLR1000","name":"Solr, the Enterprise Search Server"}}

Notice that the optional fl (field list) parameter works as normal, allowing you to select the fields you want returned.

There’s also a realtime get component that can be inserted into any request handler, including the standard request handler.

The realtime get feature uses transaction logging to keep track of uncommitted updates to the index.  When a get request for a document is received, this log is checked first and retrieved from there if found.  If it’s not found, then the latest opened searcher is used to retrieve the document.  Checking the log is super fast, and IO reads from the log are fully concurrent for maximum scalability.

Download a recent nightly build of Solr 4.0-dev and follow the Quick Start guide  on the Solr wiki.  Feedback on the solr-user mailing list is always appreciated!

Solr relevancy function queries

Lucene’s default ranking function uses factors such as tf, idf, and norm to help calculate relevancy scores. Solr has now exposed these factors as function queries.

  • docfreq(field,term) returns the number of documents that contain the term in the field.
  • termfreq(field,term) returns the number of times the term appears in the field for that document.
  • idf(field,term) returns the inverse document frequency for the given term, using the Similarity for the field.
  • tf(field,term) returns the term frequency factor for the given term, using the Similarity for the field.
  • norm(field) returns the “norm” stored in the index, the product of the index time boost and then length normalization factor.
  • maxdoc() returns the number of documents in the index, including those that are marked as deleted but have not yet been purged.
  • numdocs() returns the number of documents in the index, not including those that are marked as deleted but have not yet been purged.

We can use these new functions to develop and test custom ranking functions!  For example, if we wanted simple tf*idf for a given term, we could issue the following function query (if you have solr’s example server running with exampledocs indexed, just click on the following link):

http://localhost:8983/solr/select/?fl=score,id&defType=func&q=mul(tf(text,memory),idf(text,memory))

To avoid repeating the term we are using (text,memory) we can pull the field and term out into other query parameters:

http://localhost:8983/solr/select/?fl=score,id&defType=func&q=mul(tf($f,$t),idf($f,$t))&f=text&t=memory

Utilizing Solr’s new ability to sort by arbitrary function queries, we could now sort a query by the number of times a specific term appears in each document.  The following query searches for documents matching “DDR”, but then sorts by the number of times “memory” appears in the text field.

http://localhost:8983/solr/select/?fl=score,id&q=DDR&sort=termfreq(text,memory) desc

We could also utilize the “norm” function to sort by the longest field first.  This assumes there were no index time boosts and thus the norm is just the standard length normalization factor.

http://localhost:8983/solr/select/?fl=score,id&q=DDR&sort=norm(text) asc

Given Solr’s plethora of function queries (including the new spatial queries that return distance between points), the possibilities are almost endless.  To try this out,  you’ll need a recent nightly build of Solr 4.0-dev, or LucidWorks Enterprise, our commercial version of Solr.

Solr Result Grouping / Field Collapsing Improvements

I previously introduced Solr’s Result Grouping, also called Field Collapsing, that limits the number of documents shown for each “group”, normally defined as the unique values in a field or function query.

Since then, there have been a number of bug fixes, performance improvements, and feature enhancements. You’ll need a recent nightly build of Solr 4.0-dev to try it out.

One improvement is the ability to group by query via the group.query parameter. This functionality is very similar to facet.query, except that it retrieves the top documents that match the query, not just the count. This has many potential uses, including always getting the top documents for specific groups, or defining custom groups such has price ranges.

Another useful capability is the addition of the group.main parameter. Setting this to true causes the results of the first grouping command to be used as the main result list in a flattened response format that legacy clients will be able to handle.

For example, the grouped response format normally returns highly structured results under “grouped”. …&q=solr+memory&group=true&group.field=manu_exact


"grouped":{
"manu_exact":{
"matches":6,
"groups":[{
"groupValue":"Apache Software Foundation",
"doclist":{"numFound":1,"start":0,"docs":[
{
"id":"SOLR1000",
"name":"Solr, the Enterprise Search Server",
"manu":"Apache Software Foundation"}]
}},
{
"groupValue":"Corsair Microsystems Inc.",
"doclist":{"numFound":2,"start":0,"docs":[
{
"id":"VS1GB400C3",
"name":"CORSAIR ValueSelect 1GB 184-Pin DDR SDRAM Unbuffered DDR 400 (PC 3200) System Memory - Retail",
"manu":"Corsair Microsystems Inc."}]
}},
[...]

If we add group.main=true to the request, then we get back a much more familiar looking response (i.e. it looks like a normal non-grouped response): …&q=solr+memory&group=true&group.field=manu_exact&group.main=true


"response":{"numFound":6,"start":0,"docs":[
{
"id":"SOLR1000",
"name":"Solr, the Enterprise Search Server",
"manu":"Apache Software Foundation"},
{
"id":"VS1GB400C3",
"name":"CORSAIR ValueSelect 1GB 184-Pin DDR SDRAM Unbuffered DDR 400 (PC 3200) System Memory - Retail",
"manu":"Corsair Microsystems Inc."},

One can also use the group.format=simple parameter to select this simplified flattened response within the normal “grouped” section of the response.

Other recent enhancements include support for debugging explain, highlighting, faceting, and the ability to handle missing values in the grouping field by treating all documents without a value as being in the “null” group.

There have been a number of performance enhancements, including an improvement to the short circuiting logic… cutting off low ranking documents earlier in the process. This important optimization resulted in a speedup of about 9x for collapsing on certain fields!

Collapsing on string fields was further optimized with specialized code that worked on ord values instead of the string values. This doubled the performance yet again!

Please see the Solr Wiki for further documentation on all of result grouping’s capabilities and parameters.

Indexing JSON in Solr 3.1

Solr has been able to produce JSON results for a long time, by adding wt=json to any query. A new capability has recently been added to allow indexing in JSON, as well as issuing other update commands such as deletes and commits.

All of the functionality that was available through XML update commands can now be given in JSON. For example, you can index a document like so:

$ curl http://localhost:8983/solr/update/json -H 'Content-type:application/json' -d '
{
"add": {
"doc": {
"id" : "ISBN:978-0641723445",
"title" : "The Lightning Thief",
"author" : "Rick Riordan",
"series_t" : "Percy Jackson and the Olympians",
"cat" : ["book","hardcover"],
"genre_s" : "fantasy",
"pages_i" : 384,
"price" : 12.50,
"inStock" : true,
"popularity" : 10
}
}
}'

Of course, if you want the doc to be visible, you must do a commit. This could have been done by adding a commit=true parameter to the URL in the previous command, or we could have added a commit command within the JSON itself. This time we’ll issue a separate commit command.

curl "http://localhost:8983/solr/update/json?commit=true"

And now, we can query the Solr index and verify the document has been correctly added (requesting the results in JSON of course!) http://localhost:8983/solr/select?wt=json&indent=true&q=title:lightning

There’s more documentation on the Solr Wiki. To use this functionality, you’ll need to use a recent build of Solr 3.1 or greater.

Solr Result Grouping / Field Collapsing

Result Grouping, also called Field Collapsing, has been committed to Solr! This functionality limits the number of documents for each “group”, usually defined by the unique values in a field (just like field faceting).

You can think of it like faceted search, except instead of just getting a count, you get the top documents for that constraint or category. There are tons of potential use cases:

  • For web search, only show 1 or 2 results for a given website by collapsing on a site field.
  • For email search, only show 1 or 2 results for a given email thread
  • For e-commerce, show the top 3 products for each store category (i.e. “electronics”, “housewares”)
  • Hiding duplicate documents at query time.

In addition to being able to group by the values of a field, you can also group by the values of a function query. Given that geo search works as a function query, this also opens up possibilities for showing top query matches within 1 mile, between 1 and 2 miles, etc.

Just like faceting, we’ll be adding new functionality and making continual improvements. Result Grouping is documented on the Solr Wiki, and you will need a recent nightly build of Solr 4.0-dev to try it out (just make sure it’s dated after this post).

CSV output for Solr

Solr has been able to slurp in CSV for quite some time, and now I’ve finally got around to adding the ability to output query results in CSV also. The output format matches what the CSV loader can slurp.

Adding a simple wt=csv to a query request will cause the docs to be written in a CSV format that can be loaded into something like Excel.

http://localhost:8983/solr/select?q=ipod&fl=id,cat,name,popularity,price,score&wt=csv

id,cat,name,popularity,price,score
IW-02,"electronics,connector",iPod & iPod Mini USB 2.0 Cable,1,11.5,0.98867977
F8V7067-APL-KIT,"electronics,connector",Belkin Mobile Power Cord for iPod w/ Dock,1,19.95,0.6523595
MA147LL/A,"electronics,music",Apple 60 GB iPod with Video Playback Black,10,399.0,0.2446348

CSV formats tend to vary, so there are a number of parameters that allow you to customize the output. For example setting csv.escape= and csv.separator=%09 (a URL-encoded tab character) will use a tab separator and backslash escaping to match the default CSV format that MySQL uses.

http://localhost:8983/solr/select?q=ipod&fl=score,id&wt=csv&csv.escape=&csv.separator=%09

score id
0.98867977 IW-02
0.6523595 F8V7067-APL-KIT
0.2446348 MA147LL/A

The CSVResponseWriter is documented on the Solr Wiki, but you will need a recent nightly build (Solr 3.1-dev or Solr 4.0-dev) to try it out.